The One-Number Ranking Trap in Public Services
Learn how to read public service rankings without mistaking one score for access, quality, or purpose—and ask sharper questions before comparing places.
When a regional report ranks two public services side by side, the table may show one score and a clear winner. The one-number ranking trap is assuming that this score tells you which service works better for the people who need it. A ranking can be useful, but only if you know what was counted, whose experience is represented, and what the service is meant to do.
The trouble is not simply that a score leaves out detail. It can combine unlike tasks, hide who faces barriers, or reward a service for meeting a target that does not match its public purpose. Read the comparison as a claim to examine, not a verdict to repeat. The questions below help identify the problem and decide what to look at next.
Does the score combine different kinds of service?
A single ranking may place services together because they share a label, such as health access, employment support, or local administration. But a service can involve several distinct jobs: receiving a request, assessing eligibility, providing a response, and helping someone resolve a complicated case. A score that blends these stages can conceal where the real difference lies.
Suppose a regional comparison combines the speed of initial appointments with the completion of specialist referrals. One service could respond quickly at the first stage but leave people waiting later; another could take longer to assess a case but provide more continuity afterward. The overall rank does not tell you which pattern applies.
What to try: Find the component measures behind the overall score. If the report does not show them, look for a technical note or ask the issuing body to explain the calculation. Avoid treating a blended ranking as a direct comparison until you can tell which service tasks it combines.
Does the comparison count people who cannot get through the door?
Service quality is often judged using the people who reached the service: those who completed an application, attended an appointment, or returned a satisfaction survey. That can make access barriers disappear. People who could not travel, use the required language, meet an application deadline, or get through a phone queue may be absent from the data.
This matters especially when regions have different populations or geography. A central office may be easy to reach for residents nearby and difficult for people in remote communities. A digital application may be straightforward for some users but unusable for someone who lacks reliable internet access or needs assistance. A ranking based on completed interactions cannot, by itself, reveal who never managed to start one.
What to try: Ask how the report accounts for people who sought help but did not receive it, as well as people who may need the service but never applied. Look for information about eligibility, waiting to be seen, missed contacts, language support, disability access, and service coverage by location. Treat missing groups as an unanswered question, not evidence that everyone was served equally.
Are the regions being compared on equal terms?
Two regions can offer services with the same name while operating under different rules, resources, or responsibilities. One may handle a narrow set of cases locally; another may take on more complex needs. A regional office may also refer work to a separate agency, so its own score leaves part of the user’s experience outside the comparison.
Differences in population, travel distances, settlement patterns, and language needs can also affect what a fair comparison looks like. This does not make comparisons pointless. It means the reader should distinguish a difference in results from a difference in circumstances or service design.
Say a report compares two public benefit offices. Imagine one region handles routine renewals in person while the other routes them through a shared online center, and the local offices concentrate on complicated cases. A lower local-office score could reflect the work assigned to it, not simply poorer service. Check each office’s remit and referral arrangements before drawing a conclusion.
What to try: Compare the service definitions, eligibility rules, delivery channels, and responsibilities that apply in each place. If the report adjusts for local conditions, check which conditions it includes. If it does not, describe the ranking as a comparison of observed results, not as proof that the regions had the same task.
Does the measure reward what the service is meant to do?
A score can be accurate and still answer the wrong question. A service designed to prevent problems may be judged by how quickly it processes individual requests. A service focused on fair access may be ranked by average completion time. A narrow target can favor visible activity while overlooking whether people received an appropriate response.
Look at the measure’s relationship to the service’s purpose. A shorter wait may matter, but not if it comes with rushed assessments or avoidable referrals. A high completion rate may sound positive, but readers need to know what counts as completion and whether unresolved cases are included. The measure should be read as one aspect of performance, not as a substitute for the purpose itself.
What to try: Write down the service’s stated purpose in plain language, then ask whether each indicator reflects it. Check whether measures capture both process and outcome: for example, whether people were seen and whether their stated need was addressed. If the indicators pull in different directions, report that tension instead of collapsing it into a single winner.
What should you ask before trusting a service ranking?
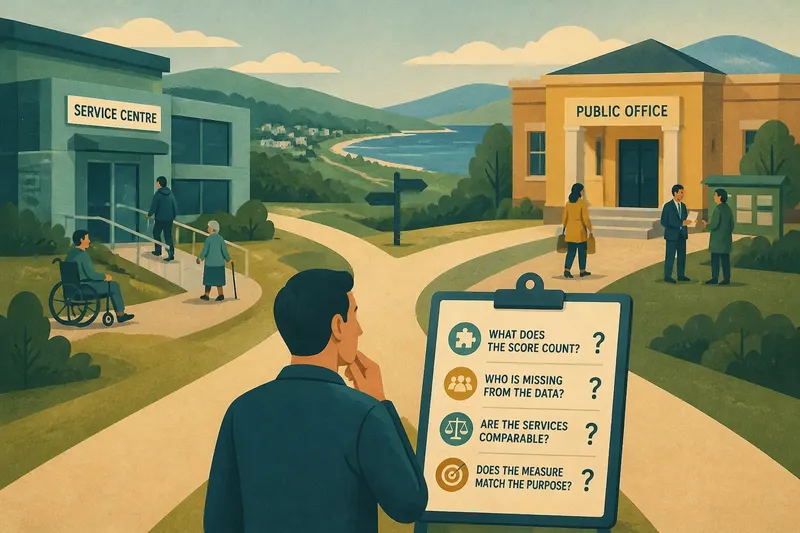
What exactly does the score count?
Check the indicator definitions, the stages of service included, and the method used to combine them. If the score is a composite, find out whether a strong result in one area can offset a weak result in another.
Who is missing from the data?
Ask whether the comparison includes people who could not apply, access the service, or complete a survey. Look for differences across location, language, disability, and eligibility where those details are available.
Are the services responsible for the same work?
Compare their formal duties, referral routes, delivery channels, and the complexity of the cases they handle. A shared label does not establish that the underlying service is alike.
Does the measure match the public purpose?
Identify what the service is expected to accomplish, then see whether the score tracks that aim or only an easy-to-count activity. A ranking that measures one useful feature should not be presented as a complete judgment.
What should you do when the ranking still seems unclear?
Do not fill gaps in the report with assumptions. State what the ranking covers, what it leaves out, and which conclusion remains uncertain. If you are preparing a briefing or discussing the comparison in a community meeting, separate observed measures from interpretation. That makes it possible to use the data without overstating its reach.
When the source allows follow-up, request the underlying indicators, definitions, and information about coverage. If the figures cannot be broken down, say so plainly. A cautious comparison can still identify a question worth investigating, such as whether access differs by location or whether one stage of service needs attention.
The one-number ranking trap is easiest to avoid when the score is treated as an entry point rather than a final judgment. Before repeating a rank, name the people counted, the service task measured, and the purpose the measure is meant to serve. That small discipline helps readers compare public services without turning a complex public obligation into a league table.